Market Demand
The exponential growth of unstructured data presents unprecedented challenges for modern enterprises. Organizations struggle with information retrieval from vast document repositories, complex codebases, and multi-format content libraries. Traditional approaches fail when dealing with ultra-long documents where critical information exists as “needles in haystacks.”
Current market solutions suffer from fundamental limitations: simplistic text chunking destroys contextual relationships, vector embeddings lose semantic coherence across document boundaries, and single-pass queries miss nuanced information patterns. Enterprise clients demand intelligent systems that can navigate complex information landscapes while maintaining accuracy and explainability.
The convergence of regulatory compliance requirements and operational efficiency needs creates a compelling market opportunity. Organizations require solutions that not only process vast amounts of unstructured data but do so with transparent, auditable methodologies that support governance frameworks.
Core Technology
Our approach transcends conventional RAG limitations through revolutionary context management strategies. Rather than fragmenting documents into isolated chunks, we implement intelligent sectioning that preserves contextual integrity while embedding comprehensive document summaries within each segment.
Multi-Criteria Summarization Engine: Dynamic content analysis generates multiple summary perspectives based on query characteristics, ensuring relevant information surfaces regardless of question complexity.
Orchestrated Query Distribution: Instead of single-pass information retrieval, our system deploys hundreds of targeted queries across intelligently segmented content, creating a comprehensive information forest that captures both explicit and implicit knowledge relationships.
Hierarchical Context Preservation: Each document section maintains awareness of the broader narrative while focusing on specific content areas, eliminating the context loss inherent in traditional chunking approaches.
Solution Architecture
Our framework operates on three integrated levels, optimizing cost-efficiency while maximizing information accessibility:
Level 1: Architectural Intelligence - Frontend models handle comprehensive codebase analysis for small projects and strategic architectural decisions for enterprise-scale implementations.
Level 2: Continuous Assistance - Flat-rate coding assistants provide consistent support for routine development tasks, ensuring productivity without cost escalation.
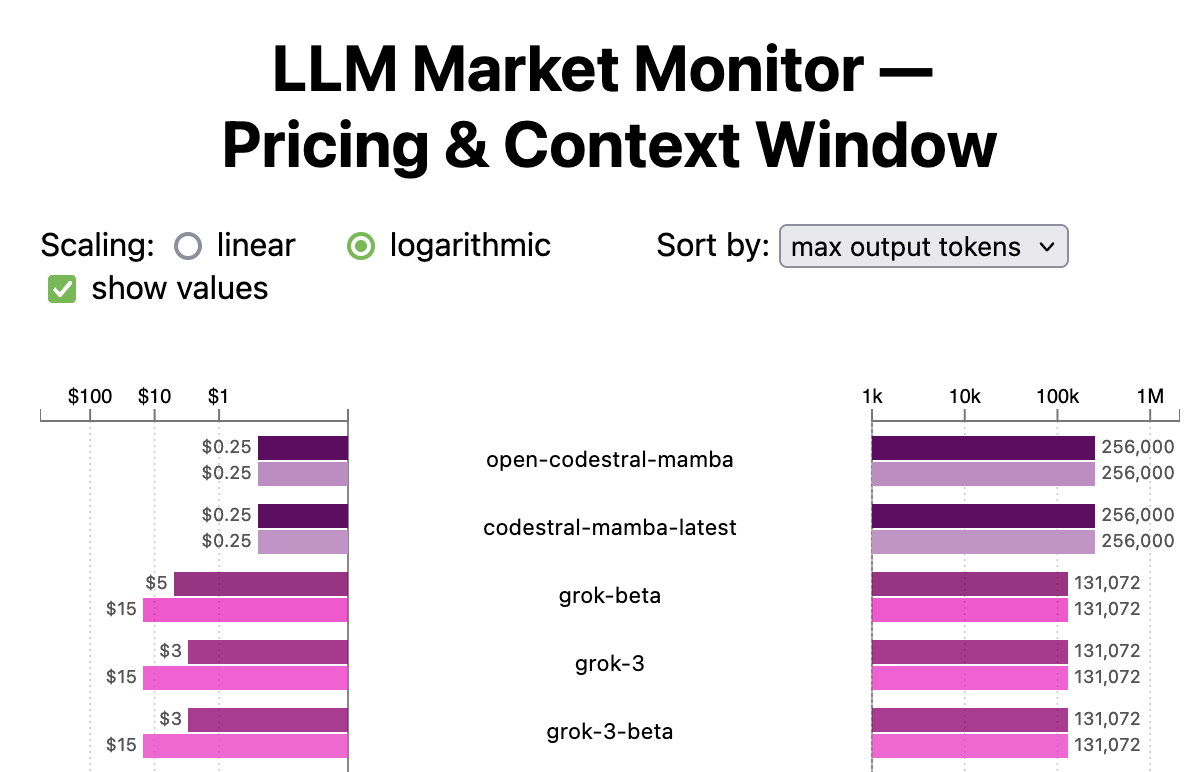
Level 3: Deep Context Processing - Local LLMs with 500K-1M token contexts tackle large-scale refactoring and complex analysis, enhanced by sophisticated RAG tooling and intelligent search capabilities.
This tiered approach ensures optimal resource allocation while maintaining consistent performance across diverse use cases. The architecture seamlessly scales from individual developer workflows to enterprise-wide information management systems.
Unique Technology Attributes
Context-Aware Segmentation: Our proprietary algorithms create document sections that maintain global awareness while enabling focused analysis, solving the fundamental trade-off between context preservation and processing efficiency.
Adaptive Query Orchestration: Multi-dimensional question deployment across content segments creates comprehensive information coverage, dramatically improving accuracy for complex queries spanning multiple document areas.
Semantic Coherence Maintenance: Advanced embedding techniques operate at sentence and concept levels rather than token-based approaches, preserving meaning across information boundaries.
Compliance-Ready Transparency: Every information retrieval operation generates auditable trails, supporting regulatory requirements while enabling continuous system optimization.
Cost-Optimized Routing: Intelligent preprocessing determines optimal context delivery strategies, balancing comprehensive analysis with operational efficiency through strategic LLM selection and RAG integration.
Our solution transforms unstructured data challenges into competitive advantages, delivering measurable improvements in information accessibility, decision-making speed, and regulatory compliance readiness.